The Liveness Probe That Killed the App When the Database Was Slow
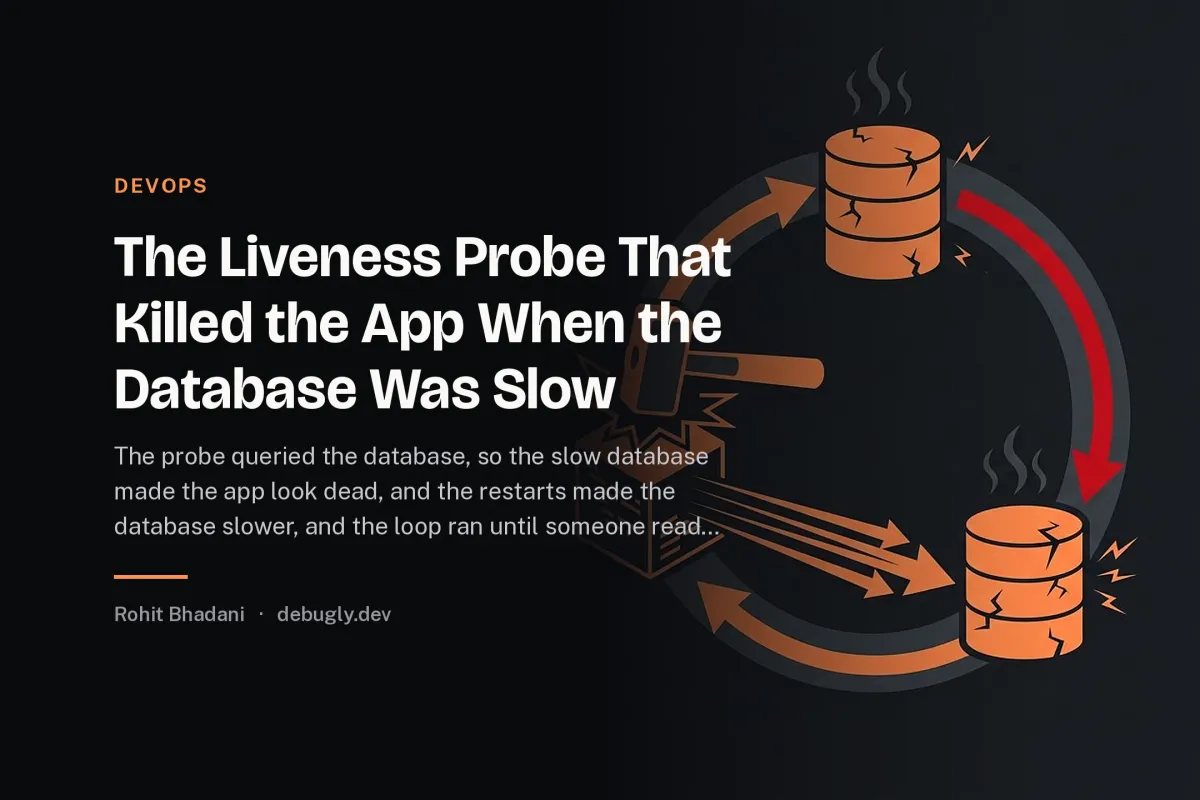
The probe queried the database, so the slow database made the app look dead, and the restarts made the database slower, and the loop ran until someone read…

Between the restarted and the loop sit 6 quiet assumptions, and the incident is the story of one of them failing.
I have run this failure in production myself, and the fix below is the one I now reach for first.
The liveness probe with a dependency has a single weak property, and here it is: the probe's failure restarts the app, and the restart adds load to the dependency, and the added load makes the dependency slower, and the slower dependency fails the probe again.
This was Kubernetes 1.30 with an HTTP liveness probe, and the mechanics are the same for any health check that reaches outside the process.
Why the probe was wrong
The liveness probe is the question of whether the process can recover by restarting, and the recover is the restart's value, and the value is the conditional on the problem's location, and the location is the process, and the process is the restart's reach, and the reach is the not the database, and the not database is the restart's uselessness, and the uselessness is the harm.
The probe checked the database, and the database was the external, and the external was the not fixed by the restart, and the not fixed was the loop, and the loop was the restart's repetition, and the repetition was the reconnect storm, and the storm was the database's load, and the load was the slower, and the slower was the timeout, and the timeout was the restart, and the restart was the loop.
The liveness should check the process's own health, and the own health is the thread's responsiveness and the memory's availability, and the two are the restart's fixable, and the fixable is the probe's domain, and the domain is the discipline, because the probe that checks a dependency converts the dependency's incident into the application's outage.
Why the readiness probe is the right place
The readiness probe is the question of whether the pod should receive traffic, and the traffic is the conditional on the dependencies, and the dependencies are the legitimate check, and the legitimate is the removal from the load balancer, and the removal is the graceful, and the graceful is the no restart, and the no restart is the fix, and the fix is the probe's separation.
The two probes are the different questions, and the different questions are the different checks, and the checks are the liveness's self and the readiness's dependencies, and the two are the discipline, and the discipline is the prevention, because the conflated probe is the restart on the unfixable.
This is the same conflation as the Kubernetes probe that restarted a healthy pod, same mechanism, different costume.
The fix, in order
Made the liveness probe check only the process. The endpoint became the in-memory check, and the check was the no external call, and the no external was the loop's absence, and the absence was the fix, and the fix was the endpoint, and the endpoint was the one route, and the route was the discipline.
Moved the dependency check to readiness. The readiness queried the database, and the queried was the traffic's removal, and the removal was the graceful, and the graceful was the fix, and the fix was the second endpoint, and the endpoint was the discipline, because the dependency's failure should stop the traffic and not the process.
Set the probe timeouts and thresholds deliberately. The timeout was the generous, and the generous was the transient's tolerance, and the tolerance was the restart's absence, and the absence was the fix, and the fix was the numbers, and the numbers were the discipline, because the tight timeout converts the slow response into the restart.
Alerted on the dependency rather than the pod. The database's latency was the alert, and the alert was the cause, and the cause was the fix's target, and the target was the right team, and the team was the fix, and the fix was the routing, and the routing was the discipline, because the pod's restart is the symptom and the database is the cause.
Tested the probe behaviour under the dependency's failure. The test was the database's slowdown, and the slowdown was the pod's survival, and the survival was the fix's verification, and the verification was the drill, and the drill was the discipline, because the untested probe is the assumed behaviour.
The takeaway
A liveness probe must check only what a restart can fix, so it should never call an external dependency; the dependency check belongs in the readiness probe, where failure removes the pod from traffic instead of restarting it. Set generous timeouts, alert on the dependency rather than the pod, and test the probe under a simulated dependency slowdown.
The database got slow and the pods started restarting, and the restarts made the database slower, and the loop ran until someone noticed the liveness probe was running a query against that same database. That is the whole pattern, and it is the part worth remembering.